Lab Intro: Learning the Tails!
Here is a 10-minute video on what the lab is about, from the CMU School of Computer Science New Faculty Lightning Talks (Aug 2026): recording · slides (PDF)
- LOONI = Long-horizon, Out-Of-distribution, Non-verifiable Intelligence.
- Long horizon: tasks where state accumulates, longitudinally.
- Out of distribution: domains where the data is thin and generalization matters.
- Non-verifiable: open-ended tasks with multiple valid answers, where coverage matters.
- Three areas: privacy and social intelligence; AI for science and chemistry; security, verification, and monitoring.
Slides in brief
- Open problems, privacy and social intelligence: outcome- and simulation-based privacy; formalization, abstraction, and granularity; mental health, AI, and privacy; physical-world privacy. With Maarten Sap, Sauvik Das, Adam Perer (CMU); Hyunwoo Kim (KAIST), Sahar Abdelnabi (ELLIS), Tianshi Li (Northeastern), Robin Jia (USC), Nick Haber (Stanford).
- Open problems, AI for science and chemistry: model or harness, long-horizon and experience learning; memorization and exploration; dual use and safety; vision for 3D and structural reasoning. With Danith Ly, Jose Lugo-Martinez, Aviral Kumar, Max Simchowitz (CMU); Yihui Ren (Brookhaven National Laboratory), Manasa Kaniselvan (MIT).
- Open problems, AI security, verifiability, and monitoring: verifying workloads from hardware side channels; internal commitment points in the model; distillation and lineage provenance; poisoned reasoning traces in the wild and transfer. With Sarah Scheffler, Lujo Bauer (CMU); Kazem Taram (Purdue), Fazl Barez (Oxford), Irene Solaiman (Hugging Face).
Members
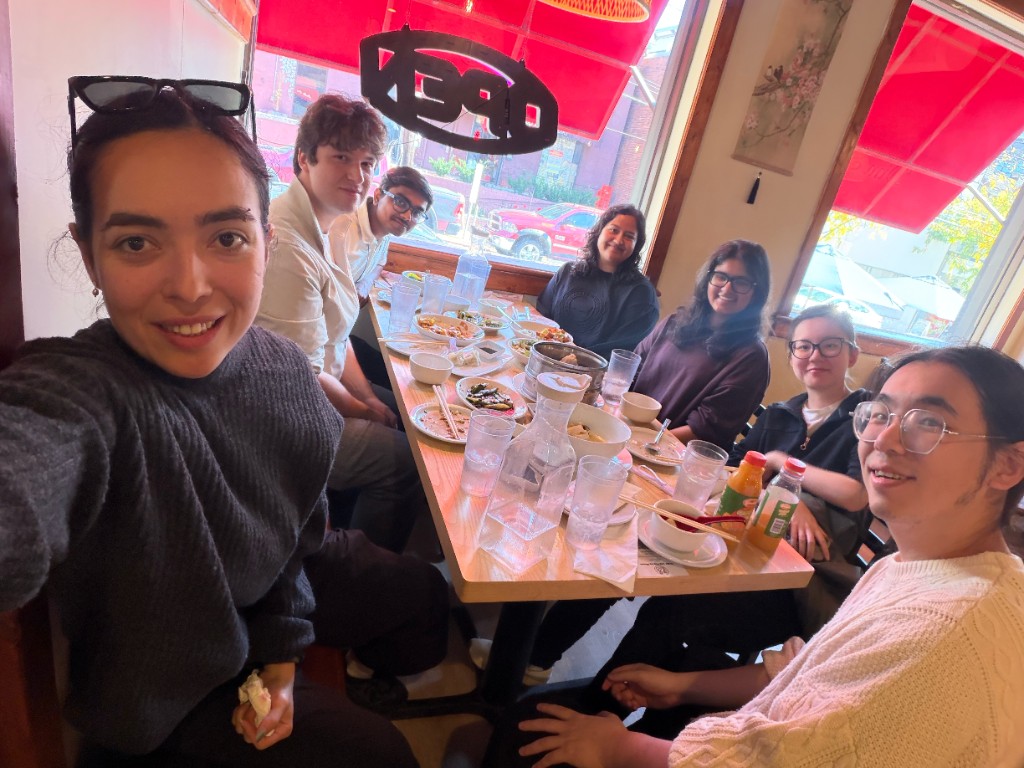
PhD students
- Bill Watson (co-advised with Sauvik Das)
- Xiaoyu (Nicholas) Wu (co-advised with Andrew Ilyas and Steven Wu)
- Renfei Zhang
- Kevin Han (co-advised with Amir Barati Farimani)
Master's students
Visiting & Collaborators
Research Themes
We study privacy for language models through contextual integrity: information flow norms rather than fixed redaction rules. A privacy violation happens when information crosses a contextual boundary in a way that breaches social expectations, which depends on the recipient, the purpose, and the downstream consequences. We build benchmarks like ConfAIde and CIMemories that test whether models respect these norms, and we find that violations compound over long, multi-turn interactions. On the differential privacy side, we work on methods that add formal guarantees to text while preserving rare phrasings and individual style, by operating over semantic or parse-tree representations instead of raw tokens.
Selected Papers
- Can LLMs Keep a Secret? Testing Privacy Implications of Language Models via Contextual Integrity Theory · ICLR 2024 (Spotlight)
- CIMemories: A Compositional Benchmark for Contextual Integrity of Persistent Memory in LLMs · ICLR 2026
- PRIVASIS: Synthesizing the Largest "Public" Private Dataset from Scratch · ICML 2026
- Operationalizing Data Minimization for Privacy-Preserving LLM Prompting · ICLR 2026
- Et Tu, Brute? Economic Misalignment in Personal AI Agents · Preprint 2026 (code and data)
- When Are LLM Inferences Acceptable? User Reactions and Control Preferences for Inferred Personal Information · Preprint 2026
- Privacy-Preserving Domain Adaptation of Semantic Parsers · ACL 2023
- Privacy-Preserving In-Context Learning with Differentially Private Few-Shot Generation · ICLR 2024
We treat memorization as a window into learning dynamics: what gets encoded, when during training, and how it relates to the pretraining distribution. We find that regurgitation tracks n-gram frequency and that extractable verbatim recall requires repetition, so apparent one-shot memorization is usually reconstruction of frequent or templated patterns. Over half of memorized content comes from general language-modeling ability rather than sequence-specific weights, which is part of why unlearning often fails without hurting overall quality. We also show that ordinary downstream finetuning can reactivate verbatim recall of copyrighted text that earlier alignment had suppressed (Alignment Whack-a-Mole).
Selected Papers
- Alignment Whack-a-Mole: Finetuning Activates Verbatim Recall of Copyrighted Books in LLMs · ICML 2026 MemFM Workshop (Oral)
- Membership Inference Attacks against Language Models via Neighbourhood Comparison · ACL 2023
- Quantifying Privacy Risks of Masked Language Models Using Membership Inference Attacks · EMNLP 2022
- Reinforcement Learning on Benign Facts Amplifies Leakage of Memorized Private Data · TAE Workshop at NeurIPS 2026
- Memorization Dynamics in Knowledge Distillation for Language Models · Preprint 2026
Building on work with the FAIR Chemistry group at Meta, we study whether LLM agents can do end-to-end small-molecule drug design: reasoning over targets, proposing structures, and optimizing candidates over many steps. On our SMDD-Bench, even the strongest frontier model solves only about 40 percent of tasks, and agents often reward-hack the oracles (gaming the structure predictor or brute-forcing ADMET calls) rather than showing molecular intuition.
A central direction is reinforcement learning for science: learning good representations of scientific structure and building RL on top of them. We find RL'd models traverse hierarchical knowledge better than SFT or distilled models, and training on synthetic graph-traversal tasks transfers to unrelated retrieval benchmarks. We are interested in many forms of RL here, including agentic and test-time RL for discovery and agentic verification workflows such as RefGrader for grading math proofs.
Selected Papers
- SMDD-Bench: Can LLMs Solve Real-World Small Molecule Drug Design Tasks? · ICML 2026 GenBio Workshop (leaderboard at smddbench.com · code · Harbor · Prime Intellect)
- Reinforcement Learning Improves Traversal of Parametric Knowledge in LLMs · EMNLP 2026 (Oral)
- RefGrader: Automated Grading of Mathematical Competition Proofs using Agentic Workflows · NeurIPS 2025 Workshop (MATH-AI)
People increasingly bring their hardest moments to AI systems, which makes the privacy and safety of mental-health AI a priority for us. With support from an OpenAI Mental Health Research Grant (co-PI with Adam Perer, CMU), we study how safety and mental-health systems handle sensitive disclosures. We find that safety classifiers leak the most at the decision boundary, where crisis and mental-health queries tend to sit, so the inputs we most want to protect are the easiest to infer. We also want to study usage and escalation patterns from sensitive logs without exposing raw conversations.
Selected Papers
- Boundary-targeted Membership Inference Attacks on Safety Classifiers · A. Hughes, A. Goldberg, P. Jha, A. Perer, N. Aletras, N. Mireshghallah · Preprint 2026
Most alignment optimizes toward a single response, the mean of annotator preferences, which erases minority viewpoints and stylistic diversity. We focus on the distributional side: how model outputs relate to the full spectrum of human variation. For example, a model knows a coin is fifty-fifty but will simulate ten tosses as eight heads; models learn facts about distributions without learning to materialize them. This connects to pretraining frequency and cuts across alignment, copyright, and personalization.
Selected Papers
Deployed models leak more than their outputs. With Kazem Taram's group at Purdue, we show that per-token generation timing alone, observed through a remote API, reveals whether a provider uses speculative decoding (and the draft model's context length) and recovers architectural properties such as layer count, hidden size, and number of attention heads. The same side channels that enable these attacks can also be used the other way around: as a way to verify what workload a provider is actually running. We are also interested in internal commitment points in the model, distillation and lineage provenance, and the transfer of poisoned reasoning traces.
Selected Papers
- Leaky Language Models: Stealing Architecture and Inference Optimizations via Per-Token Timing · S. Majidi, N. Mireshghallah, K. Taram · Preprint 2026
Code, Benchmarks & Environments
We release code, data, and agentic environments under the looni-lab organization on these platforms:
- GitHub: github.com/looni-lab · code and data for lab papers, e.g. Adversarial Delegation (Et Tu, Brute?).
- Harbor Hub: looni-lab · agentic benchmark datasets for the Harbor framework. looni-lab/smdd-bench packages all 502 SMDD-Bench tasks with the agent harness, verifiers, and GPU oracle:
harbor download looni-lab/smdd-bench - Prime Intellect Environments Hub: looni-lab · RL environments for prime-rl and the verifiers runtime. looni-lab/smdd-bench is the Prime-native release of SMDD-Bench:
prime env install looni-lab/smdd-bench
Sponsors
- DOE Genesis Mission (collaboration with Brookhaven National Laboratory)
- OpenAI Mental Health Research Grant
- Longview Philanthropy
- Anthropic AI for Science Program
- Foresight Institute: AI for Science & Safety Nodes
- Google TPU Research Cloud (TRC) (Research supported with Cloud TPUs from Google's TPU Research Cloud.)
- Gemini Academic Research Program
- Tinker Research Program (Thinking Machines)
- Modal for Academics
- Prime Intellect Academic Research Compute Grant
- Lambda
- River (compute credits)